🚀 Getting Started
📋 API Configuration
VideoLingo uses an LLM for translation. TTS is optional and only needed for dubbing. Choose your own provider and model.
1. Get API_KEY for LLM:
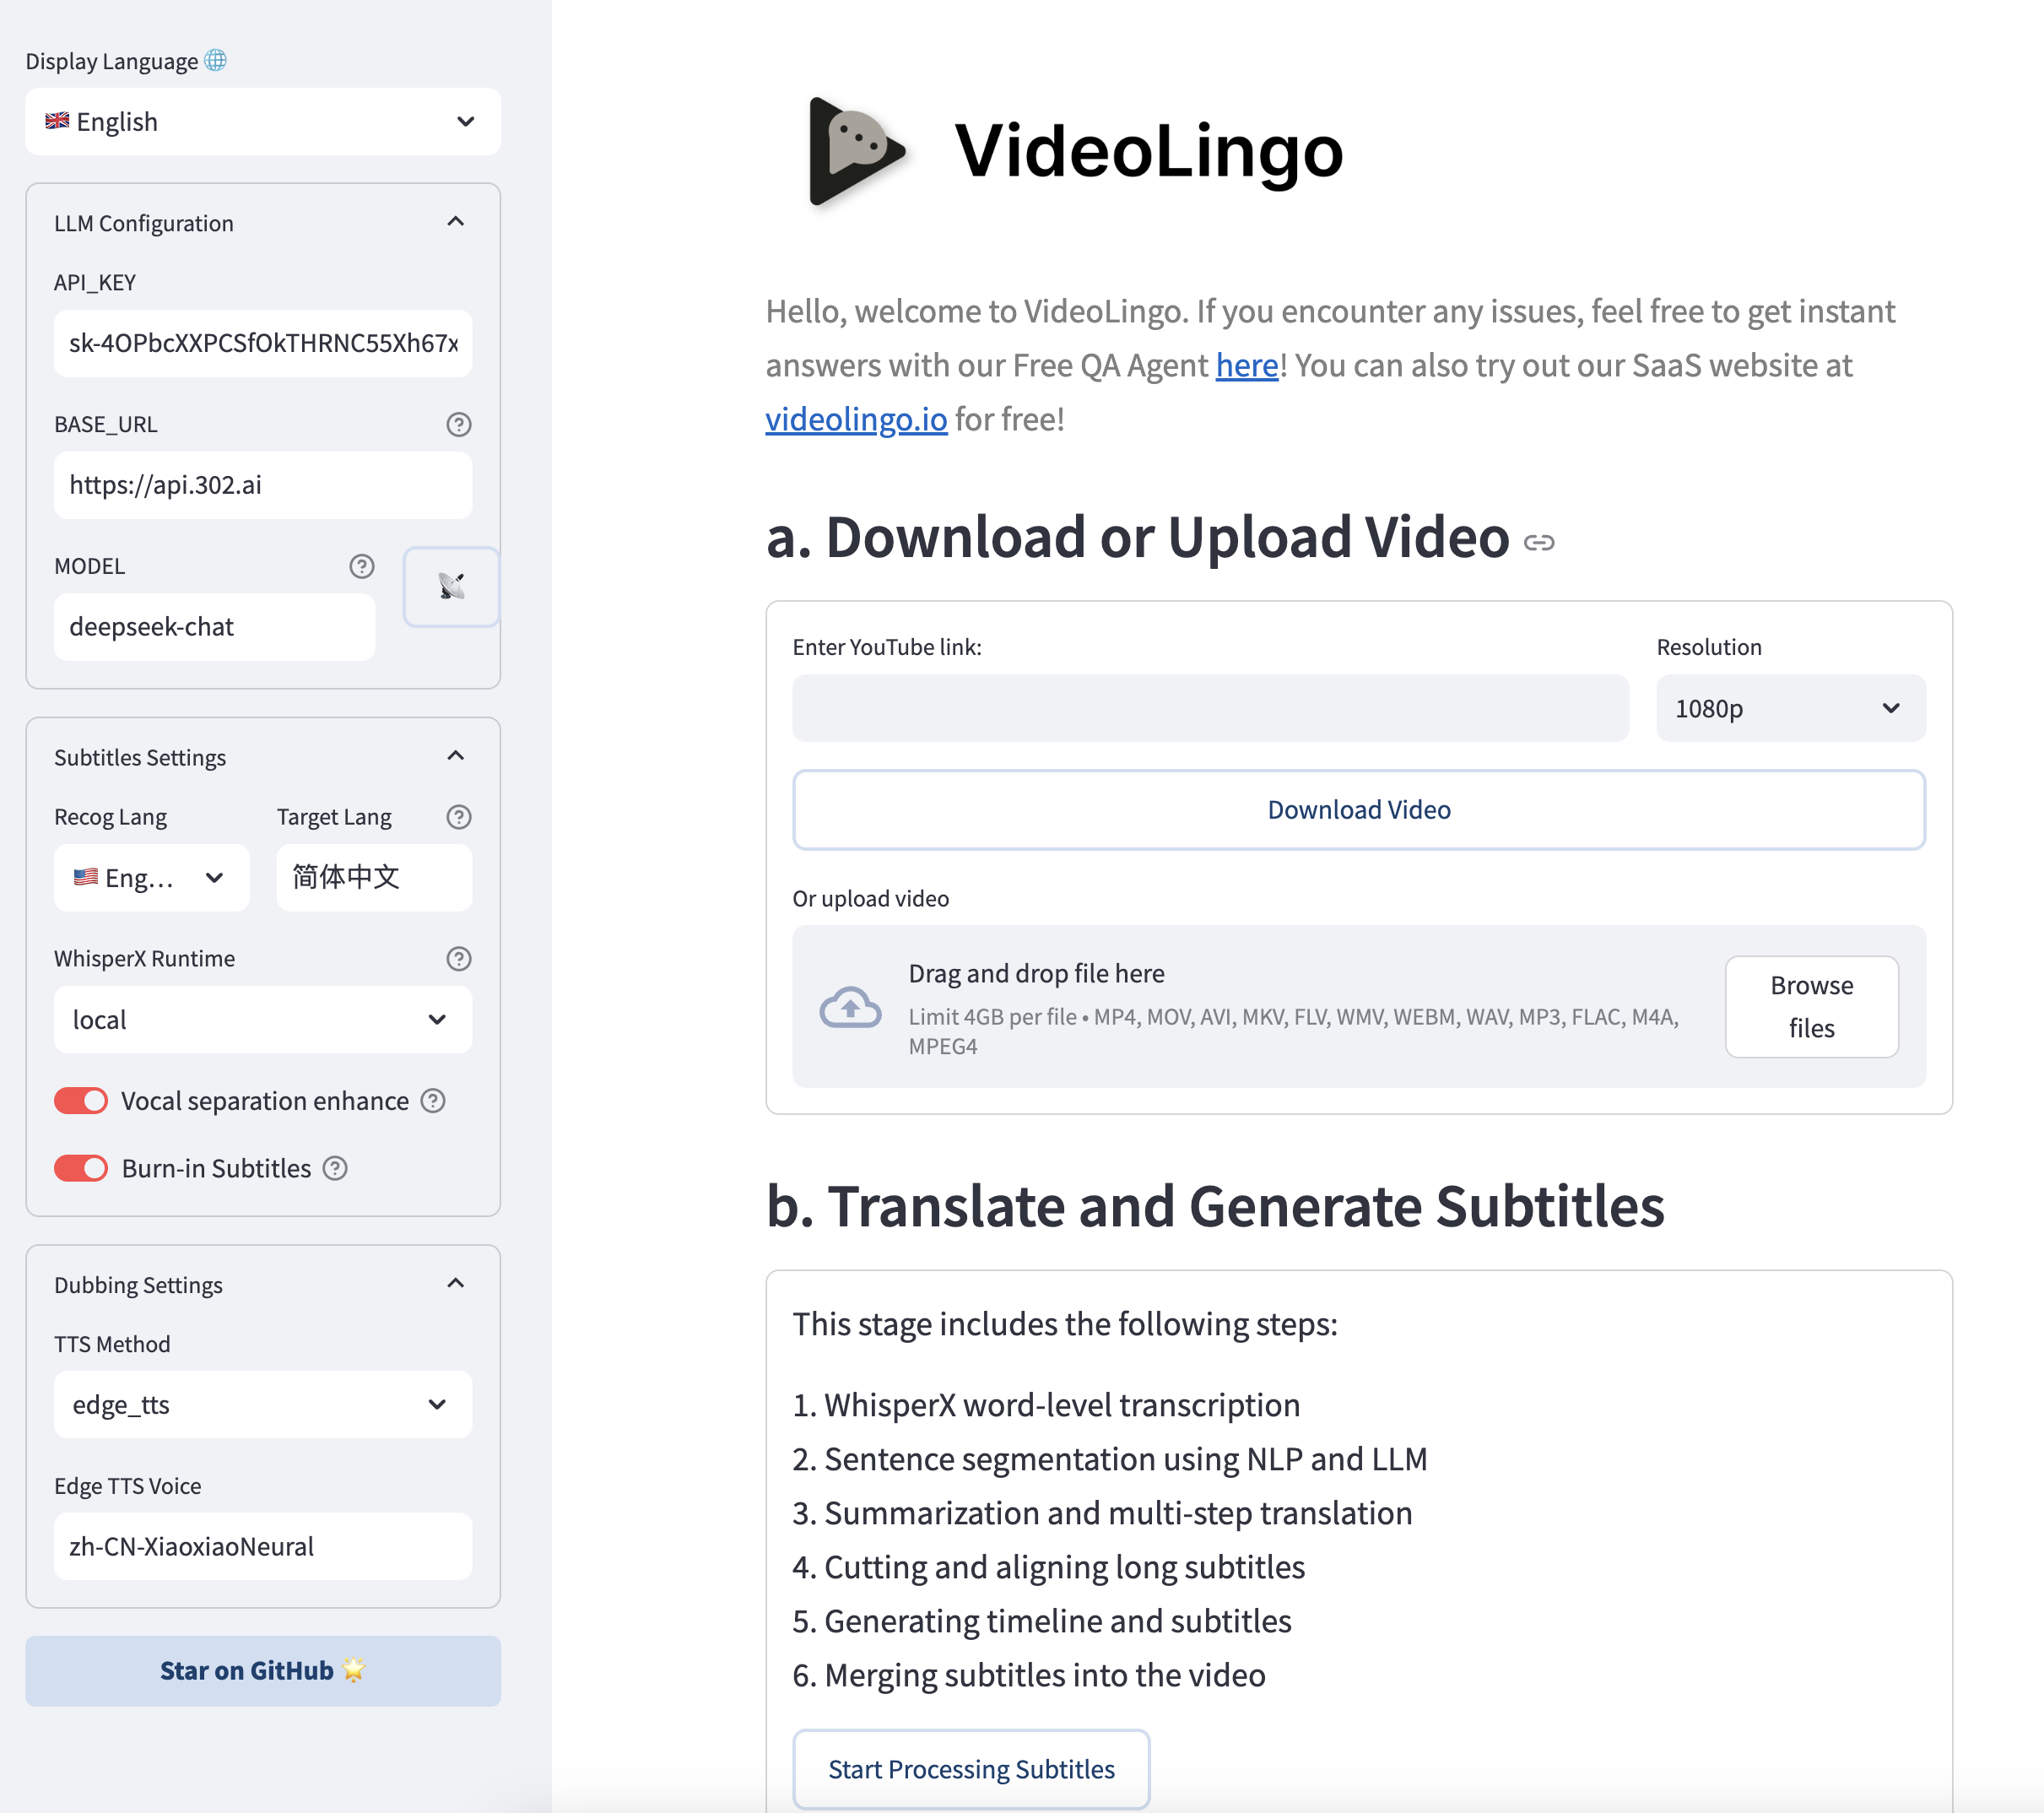
Set the API URL, key and model in the sidebar. The client uses OpenAI-compatible Chat Completions, with structured JSON required by several processing steps. Use a model supported by your endpoint; parameter count alone does not establish translation quality or JSON reliability. Enable JSON mode only if supported.
OpenLux (opens in a new tab) is the recommended relay. Set the API base URL to https://api.openlux.ai/v1. Pick one of the three models below. Prices are approximate OpenLux auto-routing group rates measured on the gateway (USD per 1M tokens; they vary by routing group):
| Recommendation | Model ID | Input | Output |
|---|---|---|---|
| Default, best value | gpt-6-luna | $0.006 | $0.029 |
| Better quality | gpt-6-sol | $0.074 | $0.37 |
| Best quality | claude-opus-5-5 | $0.71 | $3.53 |
Other OpenAI-compatible providers also work, for example OpenRouter at https://openrouter.ai/api/v1, or a local compatible server. The application requires a non-empty key field even when that server does not authenticate requests; use a placeholder only for a server that explicitly ignores the key. Edge TTS requires network access and is not an offline synthesizer.
2. TTS API
VideoLingo provides multiple TTS integration methods. Here's a comparison (skip if only using translation without dubbing)
| TTS Solution | Provider | Pros | Cons | Chinese Effect | Non-Chinese Effect |
|---|---|---|---|---|---|
| 🎙️ OpenAI TTS | OpenLux (opens in a new tab) | Realistic emotions | Chinese sounds foreign | 😕 | 🤩 |
| 🎙️ Fish Audio | Fish Audio (opens in a new tab) | Clones the voice of the video, or uses any voice of fish.audio | Paid API | 🤩 | 😃 |
| 🎙️ SiliconFlow FishTTS | SiliconFlow (opens in a new tab) | Voice Clone | Unstable cloning effect | 😃 | 😃 |
| Edge TTS | Online service | No separate API key in this adapter | Requires network access | — | — |
| 🗣️ GPT-SoVITS | Local | Best voice cloning | Only supports Chinese/English, requires local inference, complex setup | 🏆 | 🚫 |
- For SiliconFlow FishTTS, get key from SiliconFlow (opens in a new tab), note that cloning feature requires paid credits;
- For OpenAI TTS, use OpenLux (opens in a new tab) with the same key as for the LLM. Another service with the speech endpoint of OpenAI works with
openai_tts.base_urlandopenai_tts.modelinconfig.yaml; - For Fish Audio, get the key at fish.audio (opens in a new tab). The API is billed by usage and needs credit in the account; cloning costs nothing extra;
- For F5-TTS, use 302AI (opens in a new tab). It clones the voice of the video;
For a custom TTS adapter, edit
core/tts_backend/custom_tts.py.
SiliconFlow FishTTS Tutorial
Currently supports 3 modes:
preset: Uses fixed voice, can preview on Official Playground (opens in a new tab), default isanna.clone(stable): API modecustom; combines eligible reference segments from the task list, subject to text-length and duration limits, and uploads a reusable voice. This is not necessarily the first ten seconds of the video.clone(dynamic): API modedynamic; uses the current sentence's reference clip. Voice consistency and quality depend on the reference and service, with no guaranteed improvement over custom mode.
How to choose OpenAI voices?
Voice list can be found on the official website (opens in a new tab), such as alloy, echo, nova, etc. Modify openai_tts.voice in config.yaml. The default model is gpt-4o-mini-tts.
How to choose Fish Audio voices?
Select the provider Fish Audio in the page. There are two modes:
- Voice of the video (cloned): the default. The first 15-30 seconds of speech of the video are the reference of all lines. Nothing is stored in your Fish Audio account. Clone only voices that you are allowed to use.
- Fixed voice: the list has two voices,
语彤 Yutongand浩然 Haoran. For any other voice, selectAnother voice of fish.audio, find a voice that you like on fish.audio (opens in a new tab), open it and paste the address of its page or its ID.
To have your favourite voices in the list, add them with a name and their ID to fish_audio.voices in config.yaml. The model is fish_audio.model, by default s2.1-pro.
How to choose Edge TTS voices?
Edge TTS is the default and needs no API key. Run edge-tts --list-voices to list the voices, e.g. zh-CN-XiaoxiaoNeural or en-US-JennyNeural, and select one of the target language. Modify edge_tts.voice in config.yaml or in the sidebar.
GPT-SoVITS-v2 Tutorial
-
Check requirements and download the package from official Yuque docs (opens in a new tab).
-
Place
GPT-SoVITS-v2-xxxandVideoLingoin the same directory. Note they should be parallel folders. -
Choose one of the following ways to configure the model:
a. Self-trained model:
- After training,
tts_infer.yamlunderGPT-SoVITS-v2-xxx\GPT_SoVITS\configswill have your model path auto-filled. Copy and rename it toyour_preferred_english_character_name.yaml - In the same directory as the
yamlfile, place reference audio namedyour_preferred_english_character_name_reference_audio_text.wavor.mp3, e.g.Huanyuv2_Hello, this is a test audio.wav - In VideoLingo's sidebar, set
GPT-SoVITS Charactertoyour_preferred_english_character_name.
b. Use pre-trained model:
- Download my model from here (opens in a new tab), extract and overwrite to
GPT-SoVITS-v2-xxx. - Set
GPT-SoVITS CharactertoHuanyuv2.
c. Use other trained models:
-
Place
xxx.ckptinGPT_weights_v2folder andxxx.pthinSoVITS_weights_v2folder. -
Following method a, rename
tts_infer.yamland modifyt2s_weights_pathandvits_weights_pathundercustomto point to your models, e.g.:# Example config for method b: t2s_weights_path: GPT_weights_v2/Huanyu_v2-e10.ckpt version: v2 vits_weights_path: SoVITS_weights_v2/Huanyu_v2_e10_s150.pth -
Following method a, place reference audio in the same directory as the
yamlfile, namedyour_preferred_english_character_name_reference_audio_text.wavor.mp3, e.g.Huanyuv2_Hello, this is a test audio.wav. The program will auto-detect and use it. -
⚠️ Warning: Please use English for
character_nameto avoid errors.reference_audio_textcan be in Chinese. Currently in beta, may produce errors.
# Expected directory structure: . ├── VideoLingo │ └── ... └── GPT-SoVITS-v2-xxx ├── GPT_SoVITS │ └── configs │ ├── tts_infer.yaml │ ├── your_preferred_english_character_name.yaml │ └── your_preferred_english_character_name_reference_audio_text.wav ├── GPT_weights_v2 │ └── [your GPT model file] └── SoVITS_weights_v2 └── [your SoVITS model file] - After training,
After configuration, select Reference Audio Mode in the sidebar (see Yuque docs for details). During dubbing, VideoLingo will automatically open GPT-SoVITS inference API port in the command line, which can be closed manually after completion. Note that stability depends on the base model chosen.
🛠️ Quick Start
VideoLingo supports Windows, macOS (Apple Silicon / Intel), and Linux.
Ask your local AI agent 🤖
If your AI agent can operate your computer, tell it:
Install and launch GitHub's Huanshere/VideoLingo on my computer.
Windows: double-click to install 🎉
- Download Source code (zip) from the latest Release (opens in a new tab), extract it to your Desktop or another folder, and open the folder.
- Double-click
OneKeyStart.batand keep the window open. On the first run, it automatically installs uv, Python 3.12, app dependencies, and FFmpeg. An internet connection is required. - After installation, VideoLingo opens automatically in your browser. Enter your API URL, key, and model in the sidebar to start using it.
If you use an NVIDIA GPU, install a compatible driver first; see GPU runtime.
Install from source (Windows, macOS, Linux)
git clone https://github.com/Huanshere/VideoLingo.git && cd VideoLingo
uv run start.py
To start it later, run uv run start.py again from the VideoLingo folder. Apple Silicon uses MLX; Intel Macs use CPU recognition. By default, Intel Mac dubbing uses the new voice without the original background sound.
Speech recognition (Qwen3-ASR + ForcedAligner)
Local recognition transcribes with Qwen3-ASR and then produces word timestamps with Qwen3-ForcedAligner-0.6B. With vocal separation enabled, transcription uses the original audio and alignment uses the separated vocals.
- Model size:
whisper.qwen_modelinconfig.yaml(not in the sidebar).1.7b(default) is more accurate;0.6bis faster and uses less memory. The aligner is always ForcedAligner-0.6B. - Engine:
whisper.qwen_engine: autoselects it automatically; you normally do not need to change it.audiocppis an optional engine that uses a running audio.cpp server, see below.
| Platform | Engine | Models | Notes |
|---|---|---|---|
| Apple Silicon Mac | MLX (mlx-audio) | mlx-community/Qwen3-ASR-{1.7B,0.6B}-8bit, mlx-community/Qwen3-ForcedAligner-0.6B-8bit | Requires macOS 14 or newer (mlx only ships macOS ≥14 arm64 wheels) |
| Windows / Linux + NVIDIA | Official qwen-asr (transformers) | Qwen/Qwen3-ASR-{1.7B,0.6B}, Qwen/Qwen3-ForcedAligner-0.6B | cuda:0, bf16 when the GPU supports it, otherwise fp16 |
| Windows / Linux without NVIDIA | Same | Same | CPU fp32 works but is slow; prefer 0.6B or the ElevenLabs runtime |
| Intel Mac | Official qwen-asr (transformers) | Qwen/Qwen3-ASR-{1.7B,0.6B}, Qwen/Qwen3-ForcedAligner-0.6B | CPU fp32 with PyTorch 2.2.2 installed automatically; recognition is slow, so prefer 0.6B. Optional vocal separation is not installed automatically |
- On Apple Silicon the default requirements install mlx-audio, not qwen-asr; using
qwen_engine: transformersthere needs a separate environment. Below macOS 14 the installer stops with an error. If an older environment has WhisperX, rerunninginstaller.pyfirst uninstalls the WhisperX stack (whisperx, torchcodec, faster-whisper, ctranslate2, pyannote-*), which conflicts with the MLX dependencies. - Model downloads: models are downloaded from Hugging Face on first use (several GB for 1.7B plus the aligner). Set
HF_ENDPOINTto use a mirror. If_model_cache/<last part of the repo id>/config.jsonexists (for example_model_cache/Qwen3-ASR-1.7B), that local copy is used. - Languages: every recognition language in the sidebar is supported (Qwen3-ASR supports 30 languages). With
Auto, each window of about 3 minutes is first probed with up to three 20 s clips, the clips vote on the language, and the window is then transcribed with that language forced (recognition takes about a third longer); for mixed speech the first language reported is treated as primary. IfAutodetects a language outside the sidebar list (e.g. Korean, Vietnamese, Thai), sentence splitting picks a spaced or unspaced joiner automatically and uses the matching spaCy pipeline, or punctuation-only splitting when spaCy has none. - Degenerate output: if a window's transcript is one phrase looping, or much shorter than what its probe clips heard, it is retried in 60 s windows; if it is still degenerate, recognition stops with an error asking you to set the language, instead of passing a broken transcript on. With a manually selected language, a window whose transcript is unusually sparse (under 2 letters/digits per second) is checked against a few auto-language probe clips; if they heard far more it fails, and if the probes heard a different language it fails right away with a hint that the selected language may not match the audio (use auto or switch the model size), instead of passing a retry in another language downstream. A transcript whose writing system clearly does not fit the selected language (e.g. Korean text with English or Chinese selected, Japanese with almost no kana) fails the same way; that check reads the text only, adds no recognition time and runs after each window, so it stops at the first mismatching window. Silence and music never trigger this.
- Known limitation: choosing the wrong language among languages written in Latin letters (e.g. Spanish selected for an English video) cannot be detected. The model may translate some windows into the selected language instead of transcribing what was said, leaving part original and part translation. Prefer
Auto, or double-check the recognition language before processing. - The transcription cache distinguishes backend, model size and engine; changing any of them re-runs recognition.
- WhisperX is not an installer option. To use it (including the Belle model for Chinese), install the packages yourself: WhisperX (manual install).
- The official
qwenllm/qwen3-asrDocker image can host a standalone Qwen3-ASR service, but VideoLingo does not call it directly.
Optional audio.cpp engine
audio.cpp (opens in a new tab) runs the same Qwen3-ASR and Qwen3-ForcedAligner models as GGUF files in a native server, without PyTorch. With whisper.qwen_engine: audiocpp, VideoLingo sends each window to that server and keeps everything else of the Qwen path: windows, language probes, degenerate-output checks, alignment on the vocal track and punctuation mapping. It is never selected by auto, and the installer does not install audio.cpp or its models.
- Download a build for your platform from the audio.cpp releases (opens in a new tab) (for an NVIDIA GPU, a CUDA build plus its matching
cudartpackage), and the GGUF filesQwen3-ASR-1.7B-GGUF/qwen3-asr-1.7b-q8_0.gguf(or 0.6B) andQwen3-ForcedAligner-0.6B-GGUF/qwen3-forced-aligner-0.6b-q8_0.gguffrom audio-cpp/audio.cpp-gguf (opens in a new tab). - Start
audiocpp_server --config server.jsonwith these model ids, which VideoLingo uses as the requestmodel:
{
  "host": "127.0.0.1", "port": 8080, "backend": "cuda", "lazy_load": true, "max_loaded_models": 0,
  "models": [
    {"id": "Qwen3-ASR-1.7B", "family": "qwen3_asr", "path": "/path/to/qwen3-asr-1.7b-q8_0.gguf", "task": "asr", "mode": "offline"},
    {"id": "Qwen3-ForcedAligner-0.6B", "family": "qwen3_forced_aligner", "path": "/path/to/qwen3-forced-aligner-0.6b-q8_0.gguf", "task": "align", "mode": "offline"}
  ]
}- In
config.yaml, setwhisper.qwen_engine: audiocpp, andwhisper.audiocpp_urlif the server is not athttp://127.0.0.1:8080.whisper.qwen_modelpicks theQwen3-ASR-1.7BorQwen3-ASR-0.6Bid.
Windows are at most 90 s with this engine, because the audio.cpp forced aligner rejects clips of about 115 s or more. Audio is sent to the server as 16 kHz WAV over HTTP. The transcription cache keeps audio.cpp results apart from the other engines, but does not track which GGUF files or audio.cpp version the server uses: after changing them, delete .cache/asr to transcribe again.
Optional MAI-Transcribe-2 (Azure Speech or OpenRouter)
Choose ASR Runtime → MAI-Transcribe-2 in the sidebar, then select Azure Speech or OpenRouter as the MAI provider. Azure uses whisper.mai_api_key and whisper.mai_region (a region such as eastus, a resource endpoint, or blank for detection). OpenRouter uses its own key field, whisper.mai_openrouter_api_key; no Azure region is needed. Existing configurations without whisper.mai_provider continue to use Azure. The default ASR runtime remains local Qwen3-ASR.
Azure MAI uses the fast transcription API; OpenRouter uses its dedicated audio transcription API (opens in a new tab) with model microsoft/mai-transcribe-2. Both request clean text and word timestamps. OpenRouter uploads are split into roughly two-minute clips to fit its processing timeout. Audio is sent to the selected cloud provider and may incur charges. Azure MAI-Transcribe-2 is in public preview without an SLA; check that your resource region supports it. Provider and API version distinguish cached transcripts; credentials and resource region are excluded from cache identity. The contributor's evaluation in #618 (opens in a new tab) compared MAI with WhisperX, not the current Qwen3-ASR default.
Where files are stored
| What | Location | Shared with other tools |
|---|---|---|
| Python environment | .venv in the project folder, or ~/.venvs/videolingo with setup_env.py --shared (found first by start.py and OneKeyStart.bat) | No. WhisperX, if used, must be installed into this environment |
| Recognition models (Qwen, WhisperX, aligners) | Hugging Face cache: ~/.cache/huggingface/hub, or $HF_HOME/hub when HF_HOME is set | Yes. Every Hugging Face tool reads the same cache |
| Pre-placed models | model_dir in config.yaml (default _model_cache), checked before the cache. Qwen uses _model_cache/<last part of the repo id> (for example _model_cache/Qwen3-ASR-1.7B). WhisperX uses _model_cache/<model name> (for example _model_cache/large-v3; with recognition language zh, _model_cache/Belle-whisper-large-v3-zh-punct-fasterwhisper) | Only by copying |
| FFmpeg and ffprobe | Downloaded into the environment by the installer, or the folder in VIDEOLINGO_FFMPEG_DIR | Yes, with VIDEOLINGO_FFMPEG_DIR |
The installer does not set environment variables.
To reuse what is already on your computer, set these as user environment variables before starting VideoLingo:
HF_HOME: the cache folder of another tool that already downloaded the models (for example a standalone WhisperX), so they are not downloaded again.VIDEOLINGO_FFMPEG_DIR: a folder that contains bothffmpegandffprobe. The build is checked for the filters and encoders VideoLingo needs.
uv run start.py --check lists the models found in the cache, the local model folder and the FFmpeg in use.
GPU runtime
- Install a driver compatible with your NVIDIA GPU.
nvidia-smireports the driver's CUDA capability, not an installed Toolkit version. - On hosts, the installer selects PyTorch
cu128for a reported capability >=12.8, otherwisecu126when NVIDIA is detected. An unreadable capability falls back to cu126, which is not a guarantee of compatibility with an old driver. Without NVIDIA it selects CPU packages. Compatible existing packages may be reused. - The default Qwen3-ASR runs on PyTorch and uses the CUDA runtime bundled with the PyTorch wheels; no separate cuBLAS/cuDNN installation is needed. A manual WhisperX install needs CUDA 12 cuBLAS and cuDNN 9; see WhisperX (manual install).
The installer selects Python wheels; it does not install a system CUDA Toolkit. Newer CUDA 13-capable drivers do not require CUDA 13 Python packages for this project.
HTTP API
The local HTTP API replaces Excel batch mode and shares the Streamlit pipeline. See the API guide (opens in a new tab).
🚨 Common Errors & Pitfalls
-
'All array must be of the same length' or 'Key Error' during translation:
- Reason 1: Weaker models have poor JSON format compliance causing response parsing errors.
- Reason 2: LLM may refuse to translate sensitive content.
Inspect
resp_content,respandmessageinoutput/gpt_log/error.json. Failed validation is logged separately from successful response caches. Diagnose the failing stage before clearing its cached results.
-
'Retry Failed', 'SSL', 'Connection', 'Timeout': Usually network issues. Solution: Users in mainland China please switch network nodes and retry.
-
Qwen ASR engine '...' needs the 'qwen-asr' package(ormlx-audio): the recognition package is missing. Close VideoLingo, then start it again to repair: double-clickOneKeyStart.baton Windows, or runuv run start.pyfor a source installation. On Apple Silicon, if you setqwen_engine: transformersmanually, change it back toauto. -
Qwen3-ASR could not detect the languageor... is still degenerate after retrying:Autocould not determine the language, or the transcript degenerated (a looping phrase, far too little text). Select the recognition language explicitly in the sidebar and retry, or try the other model size. -
CUDA out of memory: set
whisper.qwen_modelto0.6binconfig.yaml, or close other programs using the GPU. -
mlx cannot be resolved / no matching distribution on macOS: mlx only ships wheels for Apple Silicon on macOS 14 or newer. Upgrade macOS first.
-
WhisperX errors (
cublas64_12.dll not found, segfaults,Weights only load failed, TorchCodec, etc.): these only occur with the WhisperX backend selected; see WhisperX (manual install). -
spaCy model missing: VideoLingo normally downloads the model when it is first needed. Check your internet connection, then retry the step.
-
Torch package versions disagree: Close VideoLingo, then start it again to repair: double-click
OneKeyStart.baton Windows, or runuv run start.pyfor a source installation. Intel Macs use Torch/torchaudio 2.2.2 with torchvision 0.17.2; other platforms use 2.8.0 with 0.23.0. Keep the three packages matched. Demucs is not installed automatically on Intel Macs.